

Motion and Framing Primitives
Each primitive isolates one axis of our DSL. The panels show the initial and final DSL states (changed fields highlighted), and the decoded camera motion rendered around a SOMA actor.
-
← JitterArcDolly in →The camera arcs from the left side to the front and then right, shifting the perspective smoothly across the space.Initial DSLOrientation: LeftDepth: MediumCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: CenterJitter: NoneEase: NoneFinal DSLOrientation: RightDepth: MediumCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: Center
-
← ArcDolly inPedestal →The camera slowly dollies in towards the character.Initial DSLOrientation: FrontDepth: LongCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: CenterJitter: NoneEase: NoneFinal DSLOrientation: FrontDepth: Medium FullCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: Center
-
← Dolly inPedestalTilt →The camera pedestals down slowly, physically lowering its height.Initial DSLOrientation: FrontDepth: FullCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: CenterJitter: NoneEase: NoneFinal DSLOrientation: FrontDepth: FullCamera Level: GroundLookat Level: EyeDutch Angle: NormalFraming: Center
-
← PedestalTiltDutch Angle →The camera tilts down smoothly from the face to body of the character.Initial DSLOrientation: FrontDepth: FullCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: CenterJitter: NoneEase: NoneFinal DSLOrientation: FrontDepth: FullCamera Level: EyeLookat Level: KneeDutch Angle: NormalFraming: Center
-
← TiltDutch AngleLateral Truck →The camera rolls counter-clockwise into a Dutch angle, creating a strong sense of unease and psychological disorientation.Initial DSLOrientation: FrontDepth: Medium FullCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: CenterJitter: NoneEase: NoneFinal DSLOrientation: FrontDepth: Medium FullCamera Level: EyeLookat Level: EyeDutch Angle: CWFraming: Center
-
← Dutch AngleLateral TruckJitter →The camera trucks left.Initial DSLOrientation: FrontDepth: Medium FullCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: LeftJitter: NoneEase: NoneFinal DSLOrientation: FrontDepth: Medium FullCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: Right
-
← Lateral TruckJitterArc →The camera maintains a static frame but includes organic, handheld jitter to simulate motion and high intensity.Initial DSLOrientation: FrontDepth: MediumCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: CenterJitter: LowEase: NoneFinal DSLOrientation: FrontDepth: MediumCamera Level: EyeLookat Level: EyeDutch Angle: NormalFraming: Center
Model Comparisons
The same natural-language prompt is given to every method. The orange text describes the actor and the blue text the requested camera behavior. Auteur keeps the subject correctly framed while following the intended shot, where PulpMotion and LAMP drift or lose the actor.
-
← Tail TrackSide TrackDolly In →A woman runs forward through the scene. The camera tracks from the right side and switches to left, maintaining a consistent side profile of the subject.Pulp MotionLAMPAuteur (Ours)
-
← Side TrackDolly InArc →A man stands still. The camera moves from front to front-right, pushing into a close-up with a counter-clockwise dutch angle.Pulp MotionLAMPAuteur (Ours)
-
← Dolly InArcLate Track →A person runs forward in a straight line. The camera performs an arc movement from the back to the left, while getting closer.Pulp MotionLAMPAuteur (Ours)
-
← ArcLate TrackTruck →A woman runs forward. Frontal tracking shot; the camera first stays static, then rises from hip to chest level, looking at the eyes with a smooth ease-out.Pulp MotionLAMPAuteur (Ours)
-
← Late TrackTruckPedestal Up →A woman stands still in the center of the frame. The camera moves horizontally from center-right to center-left with a smooth ease-out.Pulp MotionLAMPAuteur (Ours)
-
← TruckPedestal UpAerial Track →A man stands still, looking ahead. The camera moves vertically upward from knee level to eye level, keeping the shot level.Pulp MotionLAMPAuteur (Ours)
-
← Pedestal UpAerial TrackLead Track →A person runs forward on an open path. High-angle aerial shot from behind; the camera tracks the subject with a slight handheld jitter.Pulp MotionLAMPAuteur (Ours)
-
← Aerial TrackLead TrackTilt Up →A person runs forward toward the camera. A smooth lead track camera moves backward, capturing the subject from the front.Pulp MotionLAMPAuteur (Ours)
-
← Lead TrackTilt UpDolly Out →A medium-full shot of a person standing still. The camera tilts upward from a ground-level view of the knees to reveal the face.Pulp MotionLAMPAuteur (Ours)
-
← Tilt UpDolly OutTail Track →A person stands still facing the camera. The camera moves from front-right to the front, pulling back to a medium-full shot.Pulp MotionLAMPAuteur (Ours)
-
← Dolly OutTail TrackSide Track →A man runs forward at a steady pace. The camera tracks the subject from behind, smoothly getting closer in a tail track motion.Pulp MotionLAMPAuteur (Ours)
VerseCrafter Pipeline
Inputs to VerseCrafter: object 3D Gaussians, motion trajectories, and the text prompt.
Auteur's predicted trajectory becomes the guidance signal. Toggle Scene View / Camera View on the left video to inspect the generated trajectory, then compare against the final rendered output on the right.
-
← Tail TrackOver-the-ShoulderAnchor Middle →A man and a woman are sitting faced to each other. Camera changes from over-the-shoulder perspective to a close-up to person sitting in front.Generated Trajectory / GuidanceFinal Output
-
← Over-the-ShoulderAnchor MiddleAnchor Right →There is a prisoner in the middle and two policemen next to him. Camera gets closer focusing on prisoner.Generated Trajectory / GuidanceFinal Output
-
← Anchor MiddleAnchor RightLead track →There is a prisoner in the middle and two policemen next to him. Camera gets closer to the face of policemen to the left of prisoner.Generated Trajectory / GuidanceFinal Output
-
← Anchor RightLead trackTail track →A prisoner stands in the middle with two policemen beside him. The prisoner and the two policemen walk toward the camera. The camera gradually moves closer, focusing on the prisoner while lead-tracking him.Generated Trajectory / GuidanceFinal Output
-
← Anchor RightTail track 1Tail track →A man is walking forward across the corridor with minimal yaws. Camera tail tracks him from chest level.Generated Trajectory / GuidanceFinal Output
-
← Tail trackTail track 2Quarter Arc →A man is running forward. Camera tail tracks him from back-left side and hip level, while being tilted up.Generated Trajectory / GuidanceFinal Output
-
← Tail trackQuarter ArcClose-Up →A woman is standing still. Camera starts from left profile and do a quarter arc to capture from front, while slightly elevating to eye level.Generated Trajectory / GuidanceFinal Output
-
← Quarter ArcClose-UpLead Track →A person is looking at the camera with no movement. Camera gets to an extreme close-up shot.Generated Trajectory / GuidanceFinal Output
-
← Close-UpLead TrackBack Track →A woman is walking forward steadily. Camera lead tracks her at the shoulder level and keeping the distance.Generated Trajectory / GuidanceFinal Output
-
← Scene 9Back TrackDolly-and-Tilt →A woman is slowly getting a few steps back. Camera rises from ground to eye level and gets closer.Generated Trajectory / GuidanceFinal Output
-
← Back TrackDolly-and-TiltDolly-and-Rise →A man is standing with no motion. Camera gets closer keeping the hip level, looking at the face with an upward tilt.Generated Trajectory / GuidanceFinal Output
-
← Dolly-and-TiltDolly-and-RiseOver-the-Shoulder →A man is walking forward with pace. Camera follows him while getting closer and elevating.Generated Trajectory / GuidanceFinal Output
VACE
Inputs to VACE: a Kimodo-generated control video and the text prompt.
Actor description and camera instruction are highlighted in each prompt. With Auteur's control video, the generated shot follows the requested framing; the text-only baseline (T2V) does not.
-
← Over-the-ShoulderArcCurved Path →Wild West scene set in a vast sunlit desert town, with a rugged cowboy standing still while adjusting his hat in the exact center of the frame, wearing .... The background .... Golden sand drifts lightly across the ground while the warm afternoon sun casts long dramatic shadows. The camera performs a smooth cinematic arc around the cowboy, beginning from his left side profile, slowly circling in front of him, then continuing toward his right side, revealing more of the town and desert landscape as it moves.Control VideoOursWithout Guidance (T2V)
-
← ArcCurved PathTurn →A chase sequence set deep inside a lush emerald-green forest, where a man is sprinting forward along a narrow dirt trail that curves slightly to the right through dense wilderness. Towering pine and moss-covered trees surround the path, their leaves ... The runner wears ... The camera follows him from behind in a slightly elevated aerial tracking perspective, maintaining a constant distance as if filmed by a lightweight drone or handheld stabilizer moving through the forest. The motion contains subtle realistic jitter and vibration from rapid pursuit, adding urgency and immersion without becoming shaky.Control VideoOursWithout Guidance (T2V)
-
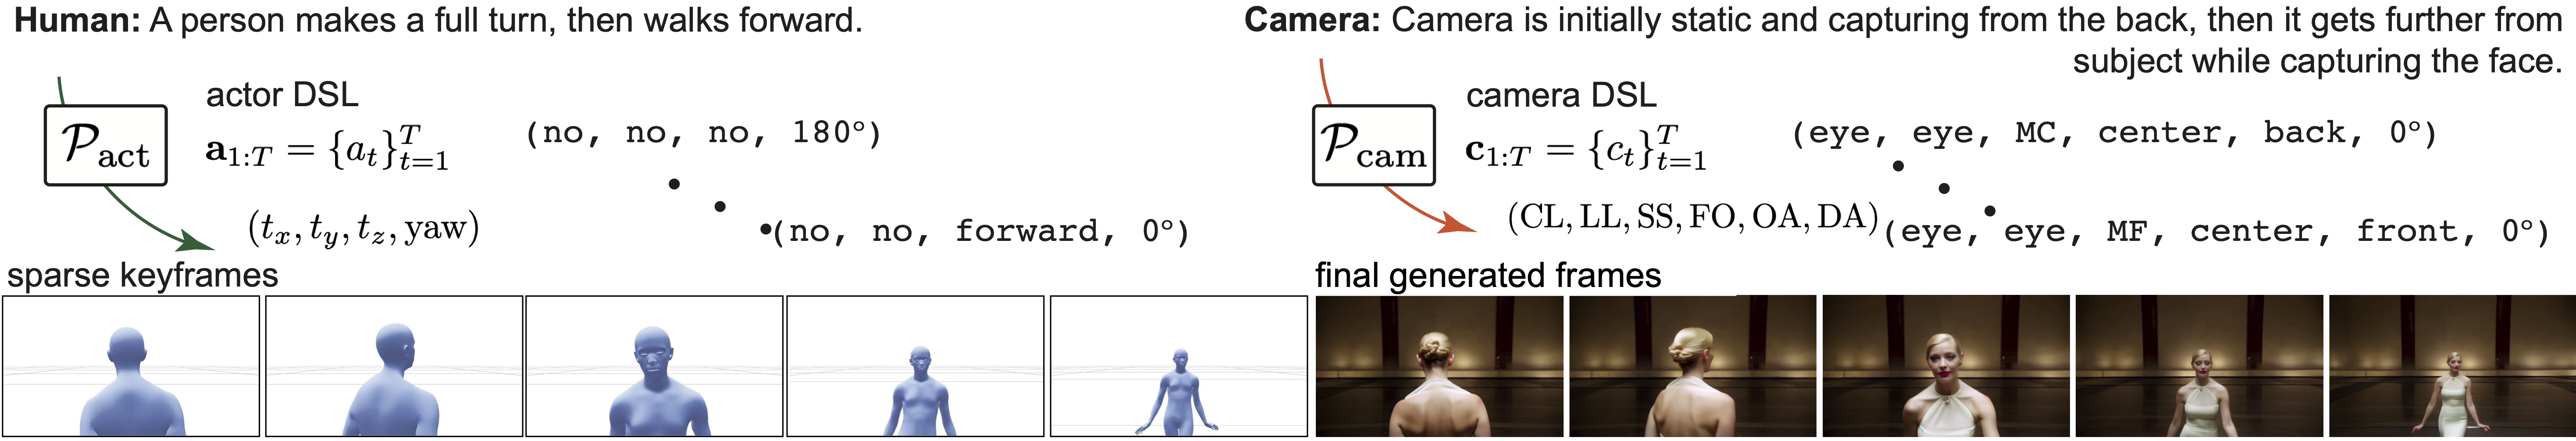
← Curved PathTurnChase →A glamorous cinematic sequence featuring Marilyn Monroe in a luxurious vintage atmosphere, wearing ... The scene begins with her standing completely still with her back facing the camera. Soft ambient lighting wraps ... The camera remains stationary at the start, creating a composed and dramatic frame focused on her from behind. After a brief pause, she slowly performs a graceful 180-degree turn toward the camera, her curls shifting naturally with the motion as her face is finally revealed in a striking cinematic moment. Her expression is ... Only after completing the turn does she begin walking forward toward the camera . As she starts moving, the camera transitions into a smooth lead tracking shot, dollying backward and getting further from her.Control VideoOursWithout Guidance (T2V)
-
← TurnChaseArc→A sci-fi desert sequence set during a sunset ... In the right of the scene, a man wearing an advanced futuristic high-tech suit runs across the desert terrain, moving forward and slightly toward the right. His suit has ... The shot begins from his left side profile. The camera dynamically tracks alongside and behind him, gradually accelerating and pushing closer throughout the sequence, tightening from a medium profile shot into an intense near-close cinematic pursuit shot. The closer the camera gets, the more visible the intricate textures ...Control VideoOursWithout Guidance (T2V)
-
← ChaseOver-the-ShoulderArc→A darkly cinematic medieval battlefield scene inspired by the epic atmosphere of *Braveheart* ... The shot begins tightly framed from behind the head of a Viking warrior in the foreground, showing the back of his head ... frame while beyond him, slightly to the left, another Viking warrior is walking directly toward the camera . He wears ... As the second warrior advances, the camera smoothly slides past the foreground warrior and transitions into a dramatic dutch angle , creating tension ...Control VideoOursWithout Guidance (T2V)